Marginal hyperposterior
Proposition taught in Hierarchical Bayes, part of Bayesian statistics
Marginal hyperposterior
| Type | Proposition |
| Taught in | Hierarchical Bayes |
| Part | Bayesian statistics |
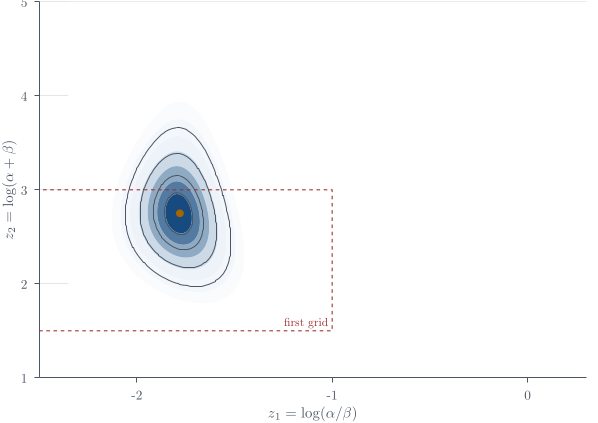
The binomial coefficient does not depend on (\alpha,\beta), so the hyperposterior kernel is \boxed{ p(\alpha,\beta\mid{\boldsymbol{y}}) \propto p(\alpha,\beta) \prod_{j=1}^J \frac{\Gamma(\alpha+\beta) \Gamma(y_j+\alpha) \Gamma(n_j-y_j+\beta)} {\Gamma(\alpha)\Gamma(\beta) \Gamma(n_j+\alpha+\beta)}}. This expression is available pointwise but is not a familiar normalised density.
Used in
- Taught in Hierarchical Bayes, where the derivation and examples are.
- All 9 questions on Hierarchical Bayes
See also
Hierarchical Bayesian model · Hyperparameter · Normal hierarchical shrinkage · Exchangeability · Empirical Bayes · Study-rate full conditional · Uniformity depends on a domain · Grid Monte Carlo approximation