Initialisation, warm-up, and dependence
Section of Markov chains, Gibbs sampling, and Metropolis–Hastings, part of Bayesian statistics
Initialisation, warm-up, and dependence
| Type | Section |
| Taught in | Markov chains, Gibbs sampling, and Metropolis–Hastings |
| Part | Bayesian statistics |
Remark 1 (Warm-up is not a convergence proof). The chain should be initialised in a plausible region when one is available. A start many standard deviations from the typical set can require a long time to return, while a start at the mean of a separated mixture can lie in a low-density gap. Multiple dispersed chains help reveal failure to explore all modes; they do not repair it automatically.
Discarding early draws is called warm-up or burn-in. It limits dependence on the chosen initial state, but it is not a proof of convergence. Strong posterior correlation produces staircase-like Gibbs paths and high autocorrelation. Separated modes are harder still because a coordinate-wise move may have to cross a low-density barrier.
Thinning by retaining every kth draw reduces storage and visible serial dependence, but usually throws away usable information. Unless storage or an expensive downstream calculation is the constraint, retain all post-warm-up draws and quantify their effective sample size. Posterior means, probabilities, and equal-tailed intervals are computed from those draws; a continuous MAP is found by optimisation, not by asking which simulated value occurred most often.
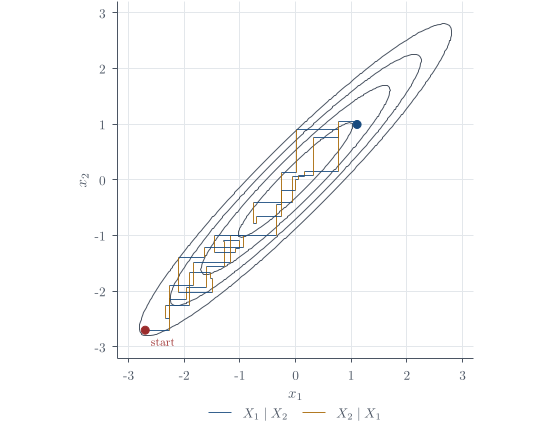
Burn-in is a practical attempt to reduce the memory of a poor starting point; it is not a theorem that the retained chain has converged. A very long run can make an initial mistake negligible, but separated modes may still defeat a sampler that never travels between them. The central question is not merely how many iterations were produced, but whether the chain explored every region whose posterior mass matters often enough to estimate their relative weights.
The deliberately absurd comparison is between 100{,}000 draws and 100 billion draws. A fixed number of poor initial draws becomes negligible as a proportion of an enormous run. That arithmetic does not help if an important remote mode is never visited: the question is whether such a region would appear in a run of that length, not merely whether the denominator is large.
Raising a target density to a power, \pi(x)^c, sharpens it for c>1 and flattens it for 0<c<1. Simulated annealing gradually changes such a power or temperature so that sampling increasingly resembles optimisation.
Used in
See also
Markov chain · Stationarity and detailed balance · Detailed balance implies stationarity · Systematic-scan Gibbs sampler · Warm-up is not a convergence proof · Metropolis–Hastings update · Metropolis–Hastings invariance · Markov chains and equilibrium